
You don’t need a data center to put a language model to work. With a decent laptop or a single-GPU box, you can run strong open-weight models, point them at your documents, and even wire them into AI agents that do useful tasks on your network.
Below is a practical, human-sized guide: the tools, the models, how to start fast, and what to watch out for.
The Fast Path: Spin Up A Local Model
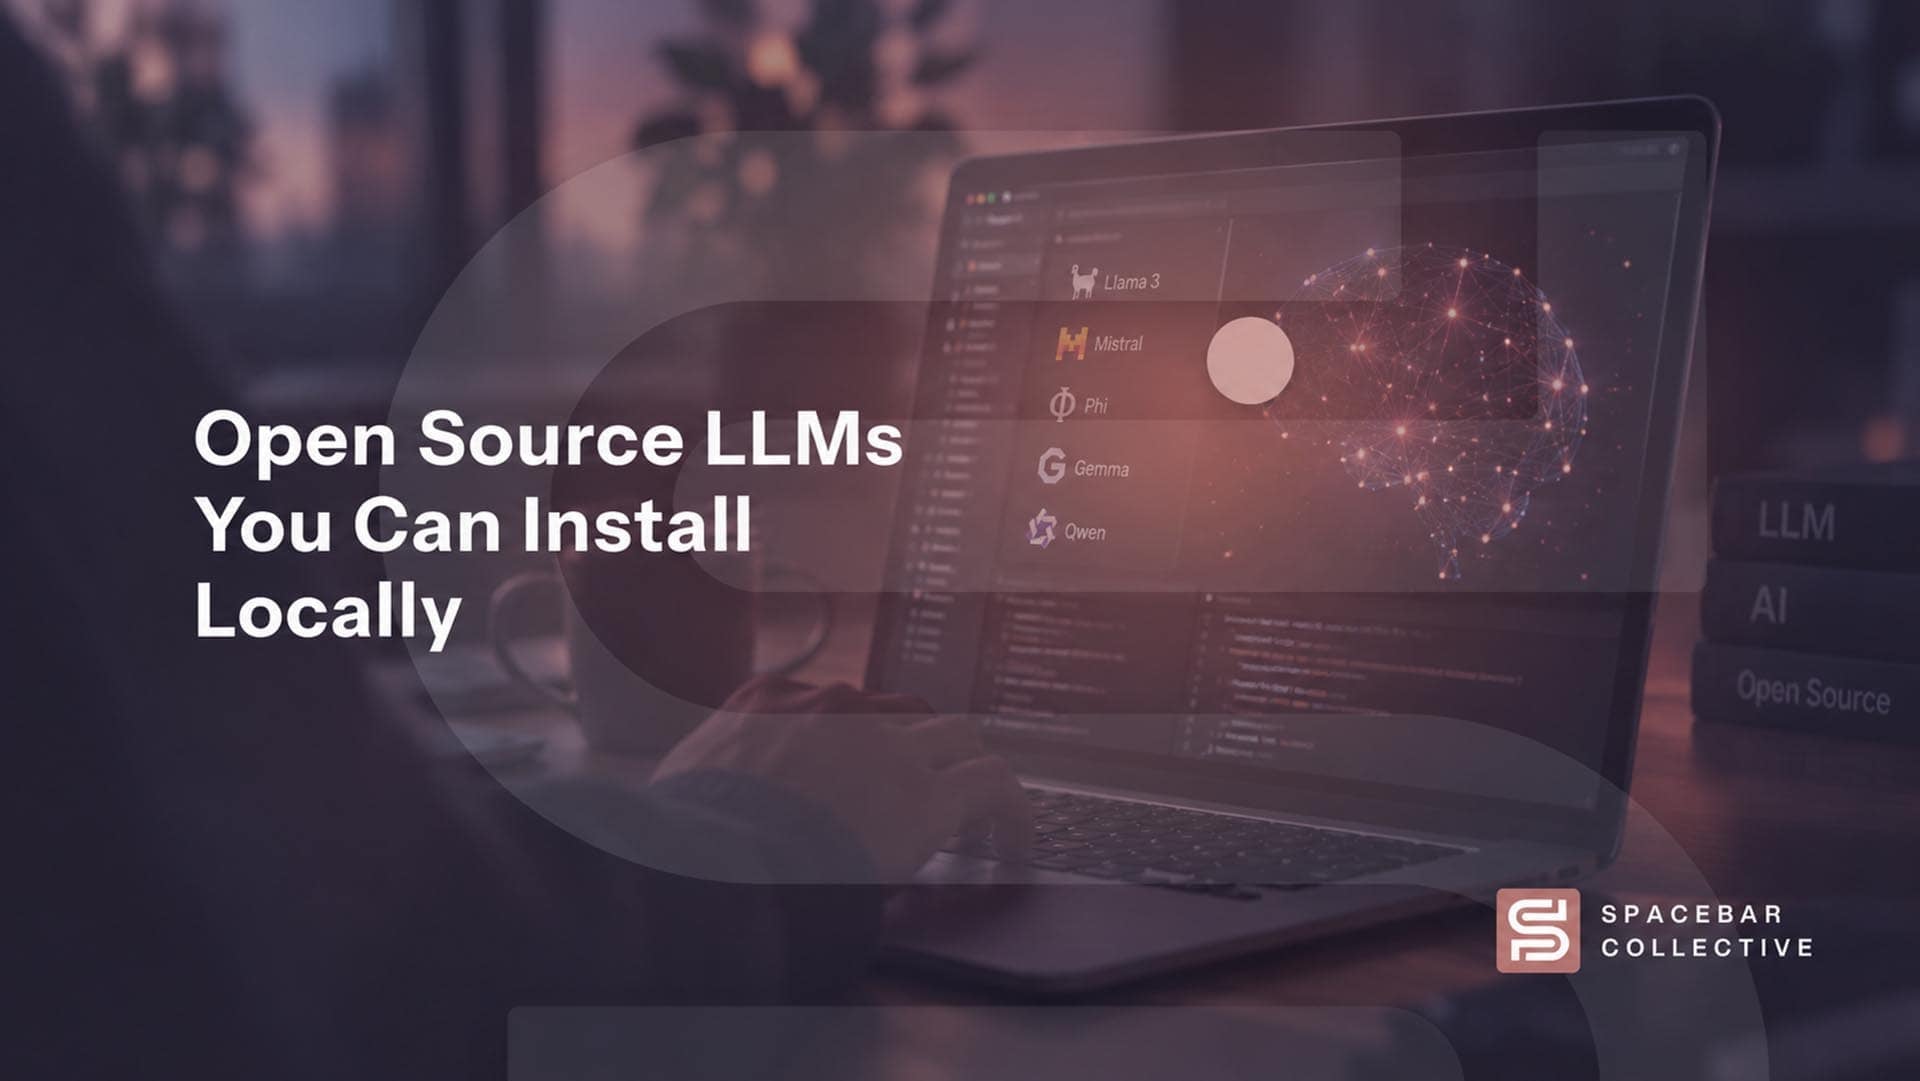
If you want the lowest-friction start, use Ollama. Install it, then run a model with one command (ollama run mistral / llama / qwen). It sets up a lightweight local API and handles downloads for you. The freeCodeCamp has a clear walk-through, including a simple Python example that chats with a local model through Ollama’s API and a reminder that 16 GB RAM with a mid-range GPU is plenty for small models.
LM Studio, Jan, GPT4All, and Llamafile are friendly options if you prefer a GUI. GPT4All is MIT-licensed, cross-platform, and designed to run local LLMs on any device, while Stream’s overview compares popular local tools and explains how llama.cpp powers a lot of them under the hood.
Going local gives you more privacy and control. Your prompts and documents stay on your machine. You also avoid per-token API bills for everyday use. Local/open models reduce vendor lock-in and keep sensitive data in-house; just remember that heavier models still require real compute.
Good Model Families to Try First
- Mistral / Mixtral. Small dense models for laptops and mixture-of-experts for extra headroom. Widely supported in local runtimes.
- Llama. Strong general models with broad ecosystem support. Check license terms for your use case. DataCamp’s list keeps Llama front and center among open options.
- Qwen. Efficient instruction models at several sizes for smooth local performance.
- Gemma. Lightweight and easy to serve locally. A solid “runs-on-my-laptop” pick.
- Magistral Small. Newer 24B open model tuned for reasoning. Worth testing on a workstation.
You don’t have to stick with one model. With Ollama or llama.cpp behind a GUI, swapping models is a dropdown away.
Make The Model Yours By Two Reliable Paths
- Retrieval-Augmented Generation (RAG)
Keep the base model frozen. Index your PDFs, wiki pages, tickets, or code in a local vector store (e.g., Chroma or Milvus Lite). At query time, fetch the most relevant chunks and pass them with the prompt. It feels like “the model reads our docs,” yet your data never leaves your machine. Both LlamaIndex and LangChain have straight-ahead RAG guides that plug into Ollama or local servers.
- Parameter-efficient fine-tuning
When you want the model to learn a specific voice, format, or workflow (not just quote your docs), fine-tune. The common recipe is QLoRA/LoRA: train small adapters on your dataset while the base stays mostly frozen. The freeCodeCamp guide even points to Unsloth for fast single-GPU fine-tunes, handy if you’re on a 24 GB card.
Which should you start with?
Use RAG to answer “what’s in our docs?” and to ground replies with citations. Move to fine-tuning when prompts get long or when you need a consistent tone/policies without stuffing the context every time. Many teams end up with both: RAG for truth, fine-tuning for style.
Turn Your Local Model Into Working AI Agents
Once your model runs locally, give it tools. That’s the step from chatting to getting things done.
- LangChain can route a local LLM to tools (search, code, DB), then back, so an agent can retrieve docs, call APIs, or write a quick script before answering.
- GPT4All doubles as a desktop app and a local inference back end you can script against, which is useful for small internal agents or offline helpers.
A simple first step towards success is a docs-triage agent that searches your local knowledge base, answers with sources, and files a ticket when confidence is low. It’s private by default and doesn’t expose your data to third-party APIs. (RAG + a small instruct model is enough.)
Source: Unsplash
A Realistic “Day One” Setup That Actually Works
- Pick a tool you’ll open daily. If you like terminals, install Ollama. If you prefer a window with buttons, grab GPT4All or LM Studio. Either way, you can swap models freely.
- Start small. Load a lightweight instruct model (e.g., Mistral, Qwen, or Gemma) and test your typical tasks: drafting, summarizing, and code notes. If responses look generic, add retrieval over a folder of your PDFs and wiki exports.
- Ground it. Use a RAG template from LlamaIndex/LangChain and point it at your local index. Benchmark on questions your team actually asks.
- Specialize if needed. If support replies or changelogs need a specific tone, fine-tune with a few thousand high-quality examples using a LoRA workflow (Unsloth/QLoRA). Keep your eval set separate so you can tell if you’re improving.
- Wrap it as an internal agent. Expose a small local API or Slack bot that uses your model and tools. Now the system is useful to everyone, not just the person who set it up.
Mind the Security Basics
Local automatically translates to safe. In late summer 2025, Cisco Talos reported more than 1,100 Ollama servers exposed on the public internet; ~20% were actively hosting models. Others have found far more in broader scans. Don’t bind your model server to a public interface without auth, and don’t run default-open Docker images on a cloud VM. Keep up with patches.
Picking the Right Local Stack (Quick Guidance)
The path forward depends on your hardware setup. If you’re on a laptop with 16 GB of RAM and a modest GPU, start with Ollama or GPT4All using a small instruct model, then add RAG over a local folder. You’ll feel the privacy and latency wins within a day.
For those with a 24 GB+ GPU, consider adding a QLoRA fine-tune for tone or structured outputs, or test a reasoning-focused open model like Magistral Small on a workstation. Serve it behind a local API to share the benefits with your team.
Final Thoughts
Give your local stack a five-minute “smoke test” before every change. Write 10 short, realistic prompts (from your own tickets), the passages they should retrieve, and the answer you expect. Keep them in a little YAML file and run them after you swap models, add documents, or tweak chunking.